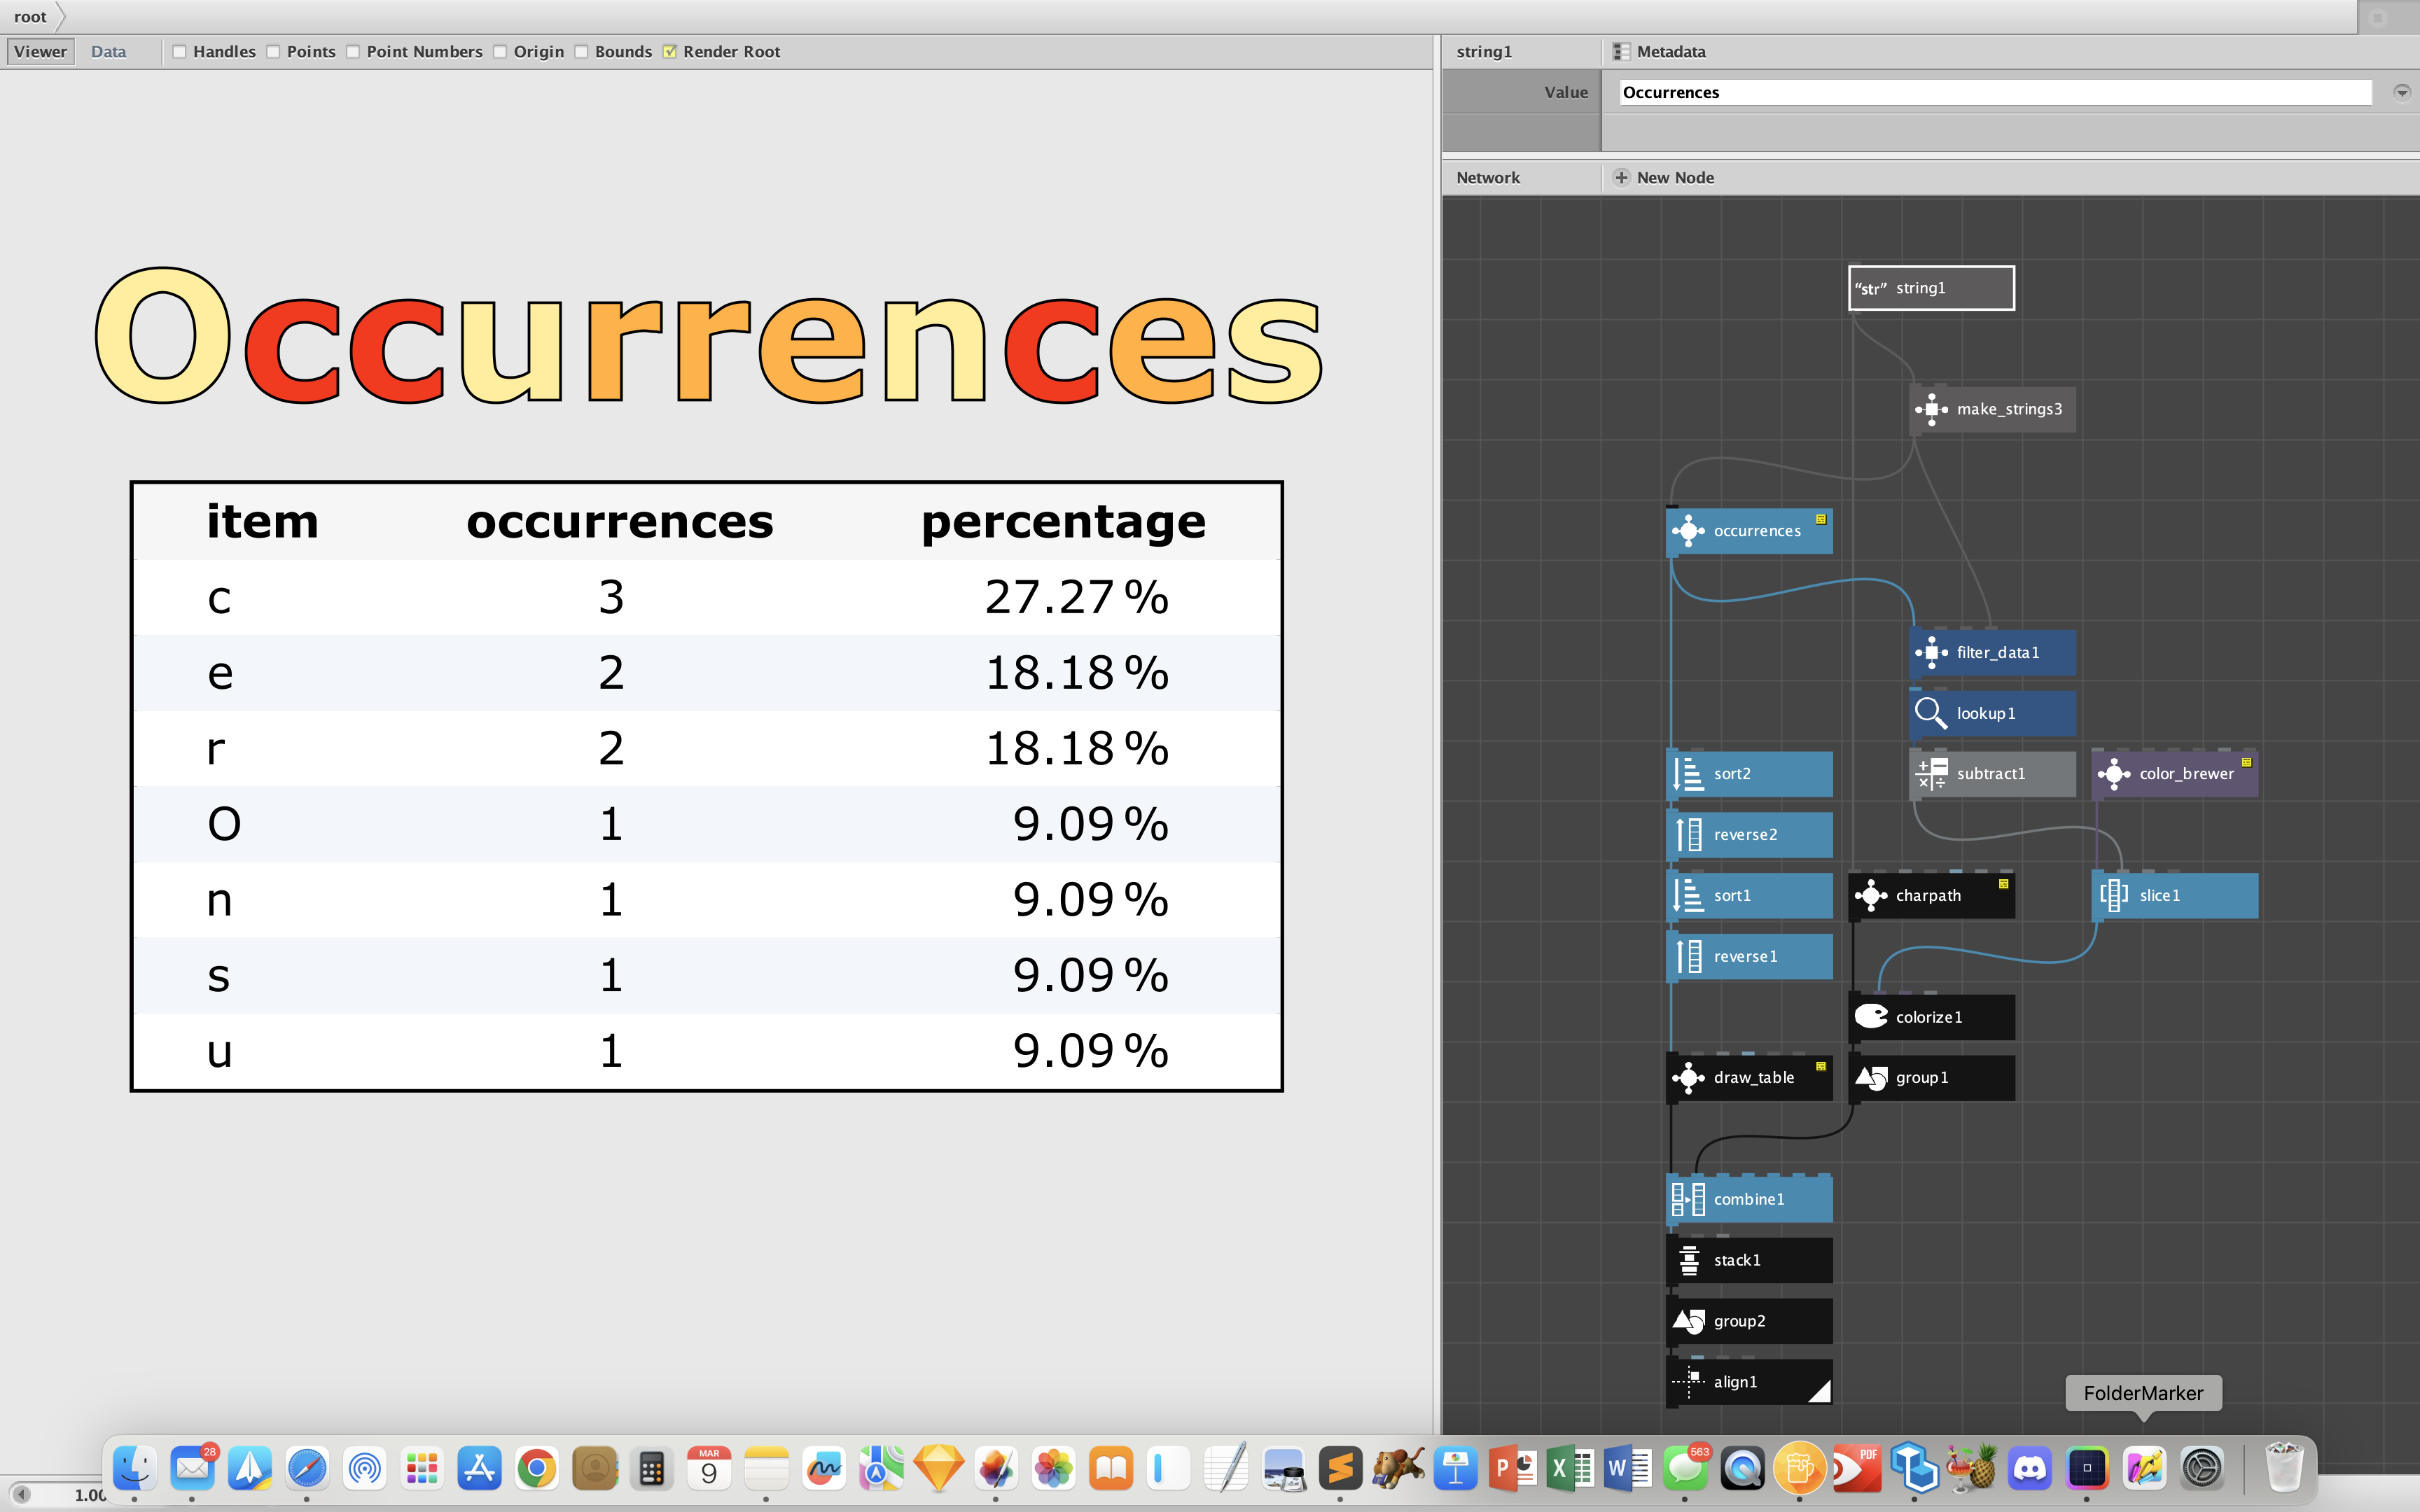
The occurrences node counts the number of occurrences of each distinct item in a list. It returns a table containing, for each distinct item, its count and percentage.
It is possible to do this calculation by converting the list to a table and using one of my data nodes, like sum_cols using the count method, but this is tedious and confusing. I just want to plug in my list and get immediate gratification.
This node is dirt simple. It takes a list as input and nothing else.
The demo uses the characters in the word "Occurrences" as a list. The table shows that the c occurs 3 times, e and r both occur twice, and the other characters only occur once. I use my color_brewer node to assign a color for each character based on how often it occurs.
I am trying not to make as many new nodes, but this one was just to useful to hide. Enjoy!